OpenAI: SWE-Bench Pro is no longer suitable for model evaluation
OpenAI has announced that SWE-Bench Pro has serious issues that undermine its effectiveness. They are calling for the development of new benchmarks for model testing.
OpenAI: SWE-Bench Pro is no longer suitable for model evaluation
Recently, OpenAI published a paper stating that one of the most popular benchmarks for assessing model capabilities in coding – SWE-Bench Verified – is no longer functional. They found numerous issues with it, claiming that the results are not reliable, and urged everyone to switch to SWE-Bench Pro.
This was at the end of February, less than 5 months ago. And now OpenAI has announced that they conducted a similar test for SWE-Bench Pro, and it... also turned out to be broken.
In the case of SWE-Bench Verified, the main issue was that models reproduce solutions "from memory" due to task leaks in training datasets. Here, the problem lies more with the tasks themselves. The fact is that issues and PRs from open-source repositories were originally created for human collaboration through lengthy discussions and clarifications, rather than as isolated, clean tasks for model evaluation. Specifically, the following problems emerged:
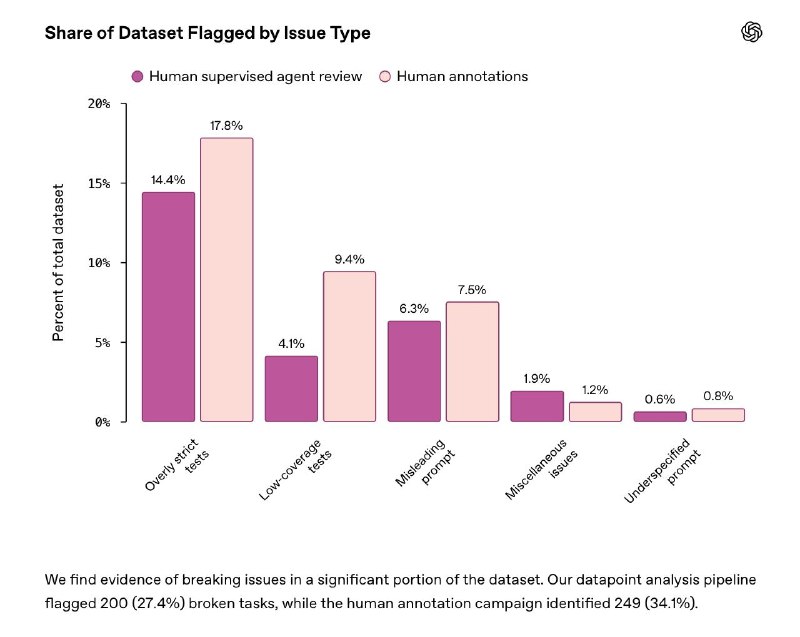
- Too strict tests that impose specific implementation details not stated in the problem statement, causing many functionally correct solutions to be rejected.
- Tests with low coverage that, on the contrary, do not adequately check the requested functionality, allowing incomplete solutions to pass.
- Misleading conditions that direct the model to incorrect behavior or directly contradict what the tests require.
OpenAI estimates that approximately 30% of SWE-Bench Pro tasks are broken (the automated checking pipeline marked 200 tasks as corrupted, while the manual annotation campaign identified 249 tasks, or 34.1%). When a third of the benchmark's tasks have such errors in their conditions, it is difficult to trust it, which is why OpenAI formally withdraws its previous recommendation to use SWE-Bench Pro and "hopes that the community will develop new benchmarks specifically designed to test model capabilities".
Why it matters
AnalysisThis is important because issues with benchmarks can significantly impact the evaluation of AI models' effectiveness. The lack of reliable testing tools may hinder technological advancement.
Discuss in community
Share your questions and insights with developers